PDF to Markdown Converter: Convert PDF Files to Markdown Online
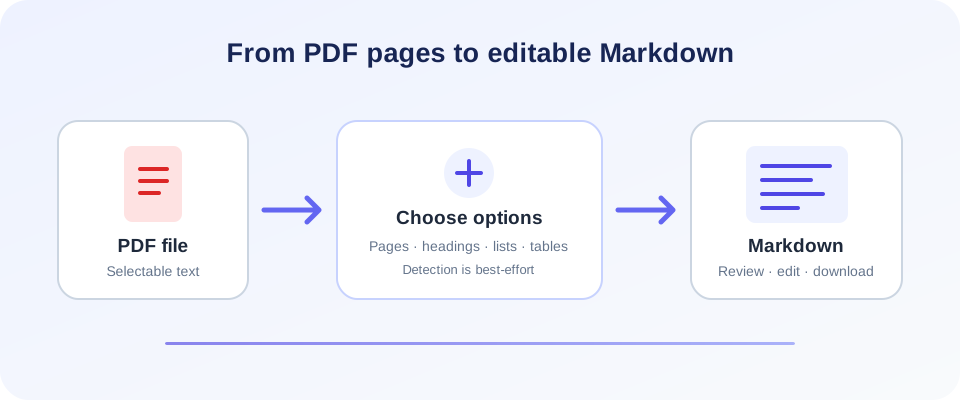
A PDF is designed to keep a page looking consistent; Markdown is plain text with lightweight syntax for headings, lists, and other basic structure. Converting between them can help when you want to edit or reuse text from a document in notes, documentation, or a text-based publishing workflow. SnapZain's PDF to Markdown converter extracts text from your chosen pages and can apply formatting rules for headings, lists, and tables.
This tool is intended for text extraction and practical reformatting—not a pixel-perfect conversion. It does not recreate colors, fonts, images, or the exact page layout. The source PDF remains the reference for checking the converted text.
How to convert a PDF to Markdown with SnapZain
If you are looking for how to convert PDF to Markdown, use the page's upload and conversion controls:
- Choose a PDF. Browse for a document or drag it into the upload area. The file must be a readable PDF no larger than 10 MB.
- Select the pages. Choose all pages, the first page, or a custom page number/range such as
2-5. - Set formatting options. Turn heading, list, and table detection on or off depending on your document and desired output.
- Convert the document. Select Convert and wait for the server-side text extraction to finish.
- Review and save. Inspect the Markdown in the read-only output box. Copy it into a text editor if you want to make changes, or choose Download to save a
.mdfile.
What the PDF-to-Markdown conversion actually does
The converter uses Poppler's pdftotext to extract text from the selected page range, then applies formatting rules to the extracted lines. It can attempt to represent some short standalone lines as level-two headings, common bullet or numbered lines as Markdown list items, and groups of space-aligned text as Markdown tables.
These options are useful starting points, but they are heuristics rather than a guarantee that the PDF's original semantic structure will be recovered. A PDF usually describes where text appears on a page; it may not explicitly identify a heading, a nested list, or a table cell. That is why converting PDF to Markdown can need a quick cleanup pass even when the extracted words look correct.
The tool produces plain Markdown text in the output box. It does not output a DOCX, HTML file, image bundle, or a Markdown file containing embedded PDF graphics. Use Download to save the text as .md.
Heading, list, and table detection: what to expect
Formatting detection can make a first pass easier to read, but the source layout influences the result:
- Headings: Short lines separated from surrounding text may be marked as level-two headings. The tool does not infer multiple heading levels from the PDF's font-size hierarchy, so verify the outline and change heading levels where necessary.
- Lists: Common bullet characters and numbered lines may be converted to Markdown list items. Nested indentation and unusual list symbols may not survive as intended.
- Tables: The converter looks for consecutive lines with repeated spacing that may indicate columns. It cannot reliably determine every cell boundary, merged cell, or multi-line value; compare table data with the PDF.
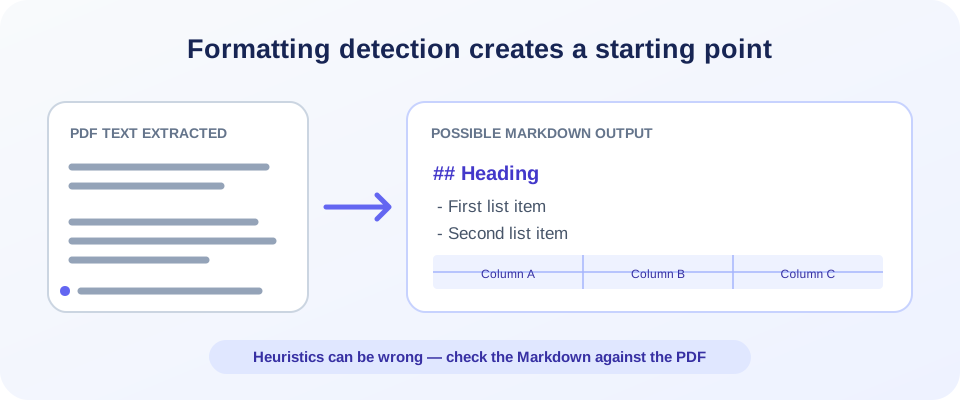
For important documents, keep the original open while reviewing the output. Check reading order, page breaks, punctuation, symbols, and any content placed in columns or sidebars. A converted file can be syntactically valid Markdown yet still need editorial correction.
| PDF content | Possible Markdown result | Useful review |
|---|---|---|
| Section title | A heading inferred from line length and surrounding text. | Check heading level and confirm body text was not promoted. |
| Bulleted or numbered text | Markdown list markers when familiar patterns are recognized. | Check nested items, sequence, and list boundaries. |
| Aligned columns | A Markdown table may be inferred from spacing. | Compare each header and cell; page alignment may not equal table structure. |
| Scanned page image | Usually no recognized text without OCR. | Run OCR separately and proofread the recognized text. |
This comparison is useful when deciding how much editing the result needs. Short narrative documents may require only heading and punctuation corrections, while reports with dense tables or multiple columns often need a page-by-page review.
Markdown uses simple characters to represent structure: a hash mark can indicate a heading, a dash can mark a list item, and pipes can separate table cells. When you edit the output, use the syntax expected by your Markdown editor and preview the rendered result. This catches issues such as a heading joined to the preceding paragraph or a table row with a missing separator.
For a long document, work through the converted text in the same order as the source pages. Check recurring headers and footers, section boundaries, and any footnotes that may have been extracted in a different position. Correcting those details before publishing can make the Markdown substantially easier to navigate.
Scanned PDFs, OCR, and extraction limits
A digital PDF often contains selectable text. A scanned PDF may contain only page images. This converter relies on text extraction and does not include OCR, so it cannot recognize words that exist only as pixels in a scan. An image-only file may produce little or no Markdown text.
If you need text from a scan, use an OCR workflow first, check the recognized words against the page images, and then try converting the resulting searchable PDF. OCR quality can vary with scan resolution, page rotation, contrast, and language. Complex multi-column layouts, decorative fonts, headers, footers, and tables can also affect reading order even in a text-based PDF.
When Markdown is useful—and when another format fits better
Markdown is a practical choice when you plan to edit text in a Markdown editor, maintain documentation, prepare notes, or add prose to a repository. It is human-readable and easy to revise, but it does not preserve a PDF's exact visual presentation or encode every kind of structured data.
If you need a data-oriented output instead, consider PDF to JSON. JSON and Markdown solve different problems: JSON represents data for software, while Markdown is commonly used for readable text and documentation. Choose based on what the next person or application expects.
For content that needs to become a PDF after editing, SnapZain also has TXT to PDF and RTF to PDF. If your source is vector artwork, use SVG to PDF. These tools handle different input formats; they do not import or preserve Markdown formatting automatically.
Online conversion, libraries, and choosing a method
A PDF to Markdown online workflow can be convenient for a one-off conversion because you can upload a file, select options, inspect the result, and download the text without setting up a local development environment. Choose the page range and formatting options before converting, then keep the original open while reviewing the result.
Developers researching a PDF to Markdown library, PDF to Markdown JS, or a tool such as Marker are usually comparing implementation approaches. This SnapZain converter is not a JavaScript library or the Marker project: it performs text extraction with Poppler and applies its own formatting rules. A library or specialized pipeline may be more appropriate when you need batch processing, custom parsing, OCR, or a particular output schema.
There is no universal best PDF to Markdown converter for every document. The best way to convert a PDF to Markdown depends on whether the PDF has selectable text, how complex its layout is, and how much review your workflow can accommodate. Test a representative file, compare all important values, and revise the Markdown in the destination editor before publishing or importing it.
Practical checklist before using converted Markdown
Use this short review before publishing, importing, or sharing the result:
- Compare names, dates, figures, and other important text with the source PDF.
- Check that headings are in the right places and use an appropriate hierarchy.
- Review list ordering, nesting, and table rows and columns.
- Look for missing text from scans, images, multi-column pages, or unusual fonts.
- Preview the Markdown in the destination editor before publishing it.
A PDF to Markdown tool can reduce repetitive retyping, but it cannot decide whether the converted content is accurate or ready for publication. A human review remains important when details matter.
Conclusion: convert PDF to Markdown and verify the result
SnapZain lets you convert a PDF to Markdown by uploading a PDF up to 10 MB, selecting pages, and choosing whether to attempt heading, list, and table detection. You can review the result and download it as a Markdown file. The converter extracts text; it does not include OCR or recreate the PDF's images and page design.
If you are searching for convert PDF to Markdown free or a free PDF to Markdown workflow, check current access conditions and limits on the live tool page. For any source document, especially a scan or complex layout, inspect the generated text and correct it before relying on it. That review helps make sure the Markdown is suitable for your next step.


